

Manufacturing Data Analytics: How to Investigate Defects Using Data You Already Have
// ON THIS PAGE 05
A finishing line has started rejecting more parts for scratches. The quality team can see the rejects in its inspection report, but the machine history sits in another system and setup changes live in a shift spreadsheet. Before buying another sensor, ask whether those records can show when the scratches started, which parts were exposed, and what changed.
Manufacturing data analytics starts with connecting a production event to a quality outcome. Episode 3 of AI in Swiss Industry makes the case for inspecting the records already available on the shop floor. Here’s how to put that idea to work on one line.
Choose a defect and a decision
Pick a product family, a defect code, and a decision the line can act on. For example, the quality lead needs to decide whether to inspect the first pieces after a fixture change more closely. A question about fixture changes gives the team a time window and a plausible mechanism. A request to predict every reject gives it neither.
Write down the unit of analysis. If the inspection decision applies to an individual part, use one row per part wherever traceability allows. If only lots can be linked, work at lot level and report the share of inspected parts rejected for the selected defect. Specify how rework and repeat inspections count. Without that rule, the same part can quietly enter the numerator twice.
Join the quality report to production history
Start with three exports. The inspection export needs a part or lot identifier, defect code, result, inspection time and revision of the acceptance standard. The production export needs the same identifier or a traceability crosswalk, plus the line, product family and processing window. The setup log should capture when the fixture changed and which line or station it affected.
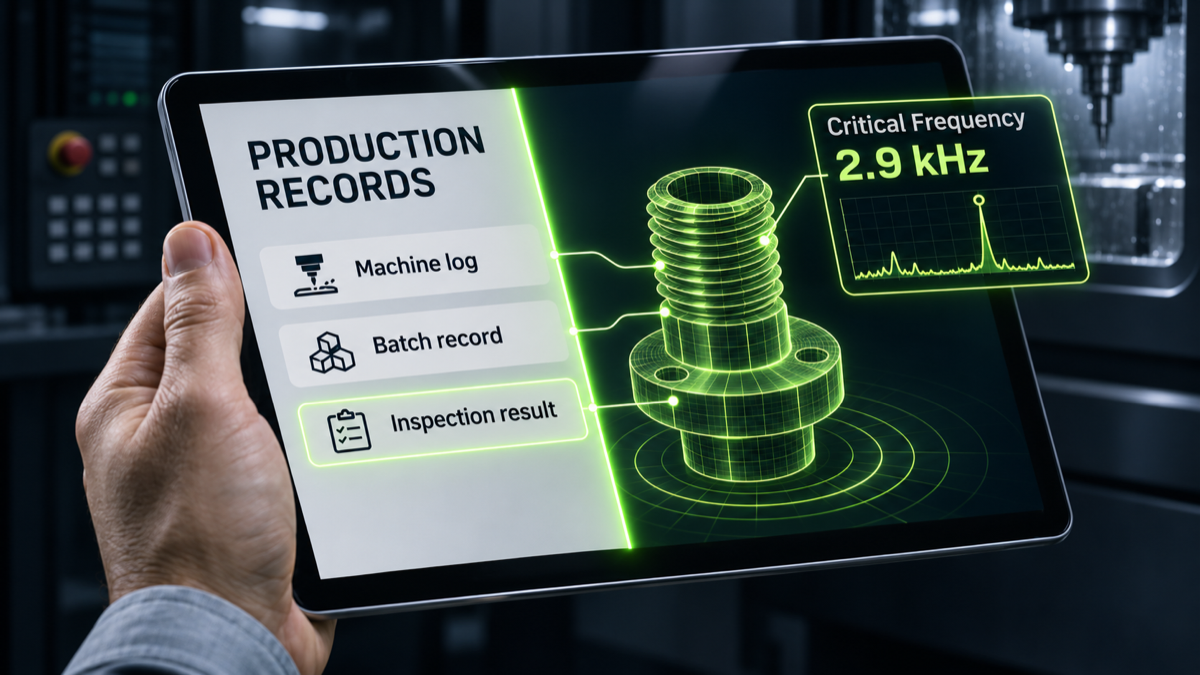
In an illustrative example, the inspection record shows that part P-0218 failed a scratch check at 10:42. Its production record places it on line 2 between 10:08 and 10:12. The setup log records a fixture replacement at 10:00. The joined row tells the team which change preceded the processing window. It does not establish that the fixture caused the scratch.
- Setup log 10:00 · Fixture changed
- Production record 10:08–10:12 · Part machined
- Inspection result 10:42 · Scratch found
Check time zones, duplicate identifiers and clock offsets before comparing events. For each line and shift, count matched inspections, unmatched inspections and ambiguous matches. Keep unmatched records visible. If the rejects are disproportionately unmatched, a dataset built from clean joins alone can hide the problem you set out to study.
Compare like with like
Compare the same product family and acceptance standard before and after the change. Normalize by the number of inspected parts, and check whether inspection frequency changed. If one shift inspects every part while another samples, the observed reject rates reflect different sampling rules.
Plot the number inspected and the number rejected alongside the rate. An apparent spike from two failures in a tiny lot deserves a different investigation from a sustained shift across several large lots. Review other changes near the same time, including material batch, tooling condition, operator handover and lighting at the inspection station.
Take the result back to the line. Ask the operators what they changed and whether the analysis aligns with what they saw. Inspect the fixture and a sample of affected parts. A suspected link becomes more useful when there is a physical explanation and a practical way to check it.
Decide whether another measurement earns its place
Use existing records when you can link the affected parts to the relevant process step and observe enough variation to test a plausible explanation. Improve recordkeeping when the problem is a missing lot ID, inconsistent defect codes or a setup change recorded without a timestamp. A barcode scan at handoff or a required setup timestamp may close that gap.
Consider a new measurement when the physical variable that matters is absent. If scratches appear during transfer and the line records only a downstream pass or fail, the available records may localize the problem without revealing contact pressure or vibration. Choose the measurement after you can state what it would distinguish and what action a reliable signal would trigger.
Siemens describes quality prediction as a use of process data in its Insights Hub documentation. That is a useful reference once your own line has a traceable outcome and observable inputs. For a plant-level example, see Embiggen X’s Siemens predictive quality analysis.
Test on a later batch before acting
If the first analysis suggests that a pattern could support an alert, freeze the decision rule and test it on a later production window. Use only fields that would have been available at the moment of the alert. Inspection results, rework notes and later measurements can explain historical outcomes, but they would leak information into a model meant to warn operators earlier.
Compare the alert with a simple baseline such as the current inspection rule. Record missed defects, unnecessary alerts and the time needed to investigate them. Keep the alert in shadow mode initially, so the team can judge whether it adds useful information without changing disposition decisions. Check whether it behaves differently by product family or shift.
Start the first review with one defect, one decision and a sample of records that the quality and production teams can trace together. That review should end with a specific next step: analyze the linked records, repair the capture process, or test a missing measurement. Discuss a quality data assessment with Embiggen X.